Understanding Regression Analysis Model Misspecification is paramount for corporate decision-makers, financial analysts, and economists who rely on quantitative modeling to guide multi-billion-dollar strategic investments.
Model misspecification occurs when an empirical regression model violates the foundational assumptions of Ordinary Least Squares (OLS) by incorrectly specifying the functional form, omitting critical explanatory variables, including irrelevant predictors, or failing to account for underlying data structures such as heteroskedasticity, serial correlation, and multicollinearity.
This comprehensive guide examines how model misspecification compromises coefficient estimates and hypothesis testing, outlines rigorous diagnostic techniques, and details practical econometric remedies to ensure robust analytical inference.
Introduction to Regression Analysis Model Misspecification in Corporate Decision-Making
In modern corporate strategy, econometric modeling serves as the backbone for financial forecasting, capital allocation, pricing sensitivity, and market expansion decisions. Executive leadership teams across multinational enterprises—such as Apple Inc., Microsoft Corporation, and Amazon.com, Inc.—depend heavily on linear regression outputs to evaluate operational efficiency and predict revenue growth.
However, the validity of any linear regression model depends entirely on whether its underlying econometric assumptions hold true. When an analyst specifies a model that deviates from the true Data Generating Process (DGP), the regression suffers from Regression Analysis Model Misspecification. Far from being an abstract theoretical concern, model misspecification can distort financial forecasts, produce false confidence in unviable projects, and result in severe misallocation of corporate capital.
To maintain analytical integrity, financial engineers and business data analysts must understand how misspecification arises, how it affects statistical inference, and how to deploy diagnostic tools and structural fixes to rectify model defects.
Understanding Regression Analysis Model Misspecification and Its Impact on Decision-Making
Econometric regression models estimate relationships between a dependent response variable  and one or more independent predictor variables
 . Under the Gauss-Markov theorem, Ordinary Least Squares (OLS) delivers the Best Linear Unbiased Estimator (BLUE) if specific classical assumptions are satisfied:
- Linearity in Parameters: The true relationship between dependent and independent variables is linear in the coefficients.
- Strict Exogeneity: The error term has an conditional expected value of zero given the independent variables,
 .
- No Perfect Multicollinearity: The matrix of regressors has full column rank.
- Spherical Errors: Error terms have constant variance (
 , homoskedasticity) and are pairwise uncorrelated (
 , no serial correlation).
When a model fails to accurately represent the true DGP, it suffers from misspecification. Misspecification corrupts statistical results in distinct ways depending on the underlying error.
The Structural Mechanisms of Model Misspecification
Model misspecification generally alters coefficient estimates, standard errors, or both. The mathematical consequences can be categorized into three severe risks:
- Parameter Bias: The estimated coefficients (
 ) systematically deviate from the true population parameters (
 ), causing misleading conclusions about the magnitude and direction of cause-and-effect relationships.
- Inconsistency: The bias does not disappear even as the sample size approaches infinity (
 ), rendering larger datasets useless for correcting the error.
- Invalid Statistical Inference: Calculated standard errors,
 -statistics,
 -statistics, and
 -values become incorrect. Analysts may reject true null hypotheses (Type I error) or fail to reject false null hypotheses (Type II error).
Common Forms of Model Misspecification and Mitigation Strategies
Omitted Variable Bias
Omitted Variable Bias (OVB) occurs when an independent variable that significantly determines the dependent variable—and is correlated with one or more included independent variables—is left out of the regression specification.
Consider a true data-generating process given by:

If the researcher omits  and estimates the underspecified model:

The expected value of the estimated slope coefficient  becomes:

The term  represents the omitted variable bias. The estimated parameter will be biased and inconsistent unless:
- The omitted variable has no relationship with the outcome variable (
 ), or
- The omitted variable is completely uncorrelated with the included predictor (
 ).
For example, if Apple Inc. models global iPhone revenue (which reached a key share of Apple’s USD416 billion total revenue in fiscal 2025) using only advertising expenditure while omitting overall consumer purchasing power, the estimated effect of advertising will be biased upward because marketing budgets and economic expansion move together.
Inclusion of Irrelevant Variables
Including an irrelevant variable occurs when an analyst adds an independent variable  whose true population coefficient is zero (
 ).
While including irrelevant variables does not introduce bias into the coefficient estimates ( ), it degrades estimator efficiency. Adding superfluous regressors inflates the variance of the remaining slope coefficients, widening confidence intervals and reducing the statistical power of -tests.
Incorrect Functional Form
Linear regression assumes that the parameters enter the equation linearly. However, economic relationships are frequently non-linear, exhibiting diminishing marginal returns, threshold effects, or exponential growth.
Specifying a purely linear model when the true relationship is quadratic or logarithmic leads to functional form misspecification. For instance, modeling corporate cost curves without quadratic or cubic terms fails to capture scale economies and eventual capacity constraints. Common functional transformations used to fix this issue include:
- Log-Linear Models (
 ): Used when the dependent variable grows at a constant percentage rate.
- Log-Log Models (
 ): Used to estimate constant elasticities (e.g., price elasticity of demand).
- Polynomial Formulations (
 ): Used to model U-shaped or inverted U-shaped relationships, such as cost curves or marginal utility.
Measurement Error in Regressors
When an explanatory variable is measured with random error ( , where
 is white noise), the regression equation develops endogenous correlation between the observed regressor and the combined error term. This induces attenuation bias, which systematically pushes the estimated coefficient toward zero (
 ), understating the variable’s true impact.
Diagnostic Procedures for Detecting Model Misspecification
To safeguard quantitative models against misspecification, analysts use several formal diagnostic tests:
- Ramsey RESET Test (Regression Equation Specification Error Test): Tests whether non-linear combinations of the fitted values (
 ) explain the dependent variable. A statistically significant RESET statistic indicates functional form misspecification or omitted variables.
- Lagrange Multiplier (LM) Tests: Evaluates general functional form restrictions and omitted variables without requiring estimation of the fully unrestricted model.
- Residual Diagnostic Plots: Graphing studentized residuals against predicted values (
 ) helps visually detect non-linear patterns, structural breaks, or severe outliers.
- Information Criteria (AIC and BIC): Comparing Akaike Information Criterion (AIC) and Bayesian Information Criterion (BIC) scores across nested and non-nested models allows researchers to balance goodness-of-fit against model complexity.
Heteroskedasticity: Types, Statistical Inference Consequences, and Remedial Frameworks
Homoskedasticity assumes that the variance of the regression error term conditional on the independent variables is constant across all observations:

When this assumption is violated, the error terms exhibit heteroskedasticity, meaning error variance differs across observations ( ).
Homoskedasticity:     Var(ε_i) = σ²       (Constant error variance across all X)
Heteroskedasticity:   Var(ε_i) = σ_i²     (Non-constant error variance dependent on X or time)
Distinguishing Between Unconditional and Conditional Heteroskedasticity
Heteroskedasticity manifests in two primary econometric forms:
Unconditional Heteroskedasticity
Unconditional heteroskedasticity occurs when error variance changes across observations but is not systematically related to the values of the independent variables. While unconditional heteroskedasticity violates classical OLS assumptions, it does not typically skew hypothesis tests as severely as conditional heteroskedasticity.
Conditional Heteroskedasticity
Conditional heteroskedasticity occurs when the variance of the error term is directly conditional on, or tied to, the magnitude of one or more independent variables or preceding time periods.
In corporate finance, conditional heteroskedasticity is extremely common in asset pricing, stock return volatility, and capital expenditure analyses. For example, evaluating corporate cash flow volatility across firms of varying sizes often reveals that larger firms exhibit substantially higher residual variance simply due to their operational scale.
Similarly, analyzing automotive delivery volatility at Tesla, Inc.—which generated USD97.69 billion in annual revenue in fiscal 2024—often demonstrates conditional heteroskedasticity: residual variance spikes dramatically during high-volume end-of-quarter delivery windows compared to baseline operational periods.
Impact of Heteroskedasticity on Statistical Inference
The presence of heteroskedasticity affects regression results in specific, technical ways:
- Unbiasedness and Consistency: OLS coefficient estimates () remain unbiased and consistent. Heteroskedasticity does not introduce systematic bias into parameter estimates because still holds.
- Loss of Efficiency: OLS estimators are no longer BLUE. The minimum variance property guaranteed by the Gauss-Markov theorem breaks down, meaning other estimators (such as Weighted Least Squares) can yield smaller sample variance.
- Biased Standard Errors: The standard standard error formulas calculated by OLS software assume homoskedasticity. Under heteroskedasticity, these standard errors are incorrect—typically understated—which inflates calculated -statistics (
 ).
- Distorted Hypothesis Testing: Underestimated standard errors produce artificially small -values. Analysts are likely to conclude that explanatory variables are statistically significant when they are not, leading to high Type I error rates.
Diagnostic Tests and Practical Remediation Strategies
To identify and resolve heteroskedasticity, quantitative analysts apply structured statistical tests and adjustments:
| Diagnostic Test | Primary Mechanism | Best Used For |
| Breusch-Pagan Test | Regresses squared OLS residuals ( ) on independent variables using an -test or LM test framework. | Detecting linear forms of heteroskedasticity tied to specific regressors. |
| White Test | Regresses squared residuals on regressors, their cross-products, and squared terms without assuming linear variance structure. | General detection of non-linear heteroskedasticity independent of functional form assumptions. |
| Goldfeld-Quandt Test | Splits data into sub-samples based on an ordering variable and compares residual variances using an -ratio ( ). | Cross-sectional datasets ordered by firm scale or revenue size. |
Remedial Frameworks
When diagnostic tests reveal heteroskedasticity, analysts use three primary solutions:
- Heteroskedasticity-Consistent (HC) Robust Standard Errors: Developed by Halbert White, Huber-White robust standard errors adjust the covariance matrix calculation directly without altering OLS point estimates:
This adjustment restores valid standard errors, -statistics, and confidence intervals for large samples.
- Weighted Least Squares (WLS): If the variance structure
 is known or can be modeled as
 , dividing the regression equation by
 restores homoskedastic errors, making WLS BLUE.
- Logarithmic Variable Transformations: Applying natural logarithms (
 ) stabilizes non-constant variance driven by exponential growth or proportional scale effects.
Serial Correlation: Time-Series Dynamics and Inference Distortions
Serial correlation (or autocorrelation) occurs when the regression error terms across different time periods (or spatial units) are correlated with one another:

Serial correlation is most prevalent in time-series corporate financial data, macro-level economic indicators, and longitudinal panels.
Understanding Serial Correlation in Business Metrics
Serial correlation is categorized by the temporal structure of the error correlation:
- First-Order Serial Correlation (
 ): The error term in period depends directly on the error term in period
 :
Where
 is the autocorrelation coefficient and
 is a uncorrelated white noise error term.
- Positive Serial Correlation (
 ): A positive error in period increases the probability of a positive error in period . This creates persistent clusters of positive or negative residuals above or below the fitted trendline.
- Negative Serial Correlation (
 ): A positive error in period increases the likelihood of a negative error in period , creating an oscillating pattern of residuals.
In time-series models for e-commerce enterprises like Amazon.com, Inc.—which reported USD716.9 billion in annual net sales in fiscal 2025—unadjusted quarterly retail sales models frequently exhibit positive serial correlation due to seasonal consumer spending trends, persistent macroeconomic shifts, and ongoing inventory expansions.
Consequences of Serial Correlation for Hypothesis Testing
When serial correlation is present, relying on standard OLS output leads to severe analytical errors:
- Unbiased Estimates under Strict Exogeneity: As long as independent variables are strictly exogenous (
 ), OLS coefficient estimates remain unbiased and consistent. However, if lagged dependent variables (
 ) are included as regressors alongside serial correlation, OLS estimates become biased and inconsistent.
- Underestimated Variance and Inflated -Stats: Under positive serial correlation (), standard OLS standard error formulas drastically underestimate true parameter sampling variance.
- Inflated Goodness-of-Fit Metrics: Standard
 and -statistics are artificially inflated, creating a false impression that the model explains more output variance than it actually does.
- Inefficient Estimators: OLS is no longer BLUE; Generalized Least Squares (GLS) provides more precise estimates.
Diagnostic Tools and Corrective Methodologies
Durbin-Watson Test
The Durbin-Watson statistic ( ) tests for first-order autocorrelation () in time-series residuals:

The test statistic ranges strictly between 0 and 4:
 : Indicates no first-order serial correlation.
 : Indicates strong positive serial correlation (
 ).
 : Indicates strong negative serial correlation (
 ).
Note: The Durbin-Watson test is invalid if lagged dependent variables () appear as explanatory regressors.
Breusch-Godfrey LM Test
The Breusch-Godfrey test addresses the limits of Durbin-Watson by testing for higher-order serial correlation ( or
 ) and remaining valid in models containing lagged dependent variables.
Corrective Strategies
- Newey-West HAC Standard Errors: Newey-West standard errors adjust for both Heteroskedasticity and Autocorrelation (HAC) without changing point estimates, ensuring valid statistical inference in large time-series samples.
- Prais-Winsten and Cochrane-Orcutt Transformations: Feasible Generalized Least Squares (FGLS) procedures estimate and transform the regression variables (
 ) to eliminate serial correlation.
- Dynamic Specification (Lagged Regressors): Adding lagged dependent variables () or explicit dynamic terms directly incorporates persistence into the structural equation.
- First Differencing: In non-stationary time series with unit roots (
 ), converting variables to first differences (
 ) eliminates serial correlation and ensures stationarity.
Multicollinearity: Structural Dependencies and Estimator Stability
Multicollinearity occurs when two or more independent variables in a multiple regression model share a strong linear relationship, making it difficult for OLS to isolate their individual impacts on the dependent variable.
Defining Perfect vs. Imperfect Multicollinearity
Perfect Multicollinearity
Perfect multicollinearity exists when one independent variable is an exact linear combination of one or more other independent variables:

Under perfect multicollinearity, the data matrix  is singular and cannot be inverted. Mathematically, OLS breaks down completely, preventing software from calculating parameter estimates. This often happens due to user error, such as including all dummy variables for a categorical variable without omitting a baseline reference group (the “dummy variable trap”).
Imperfect Multicollinearity
Imperfect multicollinearity occurs when independent variables are highly—but not perfectly—correlated in the sample data:

Imperfect multicollinearity is common in corporate finance and economics. For example, enterprise cloud models at Microsoft Corporation—which generated USD281.7 billion in annual revenue in fiscal 2025—face imperfect multicollinearity when attempting to simultaneously isolate the individual impacts of total corporate IT spending, cloud migration budgets, and software seat license expansions, as all three metrics move closely together.
How Multicollinearity Distorts Regression Outputs
Unlike model misspecification or heteroskedasticity, multicollinearity does not violate theoretical OLS Gauss-Markov assumptions. Consequently:
- Unbiased and Consistent Estimates: OLS point estimates remain unbiased, consistent, and BLUE.
- Inflated Parameter Variance: High correlation between regressors drastically increases the sampling variance of estimated coefficients:
Where
 is the coefficient of determination obtained from regressing
 on all other independent variables. As
 , variance approaches infinity.
- Low Individual -Statistics with High Overall -Statistic: Standard errors expand, producing small -statistics that make individual variables look statistically insignificant. Yet, because the underlying predictors are collectively strong, the overall model -statistic remains highly significant, and remains very high. This pattern is the classical hallmark of severe multicollinearity.
- Numerical Instability: Minor additions, deletions, or adjustments to sample data produce wild swings in coefficient magnitudes and signs.
Identification Techniques and Strategic Remedies
To detect and evaluate multicollinearity, analysts measure parameter instability and linear dependence using three primary metrics:
VIF Calculation:     VIF_j = 1 / (1 - R_j²)
Tolerance Level:     Tolerance = 1 / VIF_j
Decision Threshold:  VIF > 10 (Tolerance < 0.10) indicates severe multicollinearity requiring intervention.
- Variance Inflation Factor (VIF): Quantifies how much the variance of an estimated coefficient is inflated due to collinearity:
A VIF exceeding 10 (or a Tolerance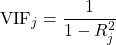
 ) signals severe multicollinearity that distorts inference.
- Condition Index: Derived from the eigenvalues of the normalized correlation matrix. A Condition Index greater than 30 indicates significant collinearity.
- Pairwise Correlation Matrices: Evaluating simple correlation coefficients (
 ) identifies highly correlated variable pairs.
Strategic Solutions
- Remove Redundant Variables: Drop one of the correlated predictors if the remaining variable captures the underlying construct effectively.
- Combine Variables: Create composite indices, averages, or ratio metrics (e.g., combining individual expenditure categories into a single investment metric).
- Principal Component Analysis (PCA): Transform correlated predictors into a smaller set of orthogonal, uncorrelated principal components.
- Ridge Regression / Regularization: Introduce a small shrinkage penalty (
 ) to the OLS optimization function to reduce parameter variance in exchange for a small amount of bias:

- Increase Sample Size: Collecting more observations adds variance to the independent variables, reducing standard error magnitudes.
Comparative Synthesis of Econometric Pathologies
The matrix below provides a side-by-side comparison of how each pathology affects regression analysis, standard errors, point estimates, and remediation options.
| Econometric Pathology | Primary Definition | Impact on OLS Coefficients | Impact on Standard Errors & Hypothesis Tests | Preferred Diagnostic Tools | Standard Remedial Framework |
| Model Misspecification (OVB / Functional Form) | Incorrect equation structure, omitted relevant regressors, or wrong mathematical function. | Biased and inconsistent. Estimates systematically deviate from population parameters. | Invalid standard errors; hypothesis tests and confidence intervals are unreliable. | Ramsey RESET test, LM tests, residual diagnostic plots, AIC/BIC comparisons. | Respecify equation, add omitted variables, apply non-linear terms or log transformations. |
| Heteroskedasticity | Non-constant error variance ( ) across observations. | Unbiased and consistent. Point estimates remain centered on true values. | Standard errors are biased (usually understated); -stats are inflated, raising Type I error rates. | Breusch-Pagan test, White test, Goldfeld-Quandt test. | Huber-White robust standard errors, Weighted Least Squares (WLS), log transformations. |
| Serial Correlation | Errors are correlated across periods or observations ( ). | Unbiased under strict exogeneity; biased and inconsistent if lagged dependent variables are present. | Standard errors are severely underestimated; -stats, -stats, and are artificially inflated. | Durbin-Watson statistic (), Breusch-Godfrey LM test, ACF plots. | Newey-West HAC standard errors, Cochrane-Orcutt transformation, dynamic models, differencing. |
| Multicollinearity | High linear correlation among two or more independent variables (). | Unbiased, consistent, and BLUE. Estimates retain long-run accuracy. | Standard errors expand drastically; individual -stats are low despite high overall and -stat. | Variance Inflation Factor ( ), Tolerance, Condition Index. | Drop redundant regressors, aggregate variables into composite indices, apply PCA or Ridge Regression. |
Conclusion and Strategic Recommendations for Executive Analytics
Regression analysis is one of the most powerful tools in corporate analytics, but its outputs are only as reliable as its underlying econometric assumptions. Unaddressed Regression Analysis Model Misspecification, heteroskedasticity, serial correlation, and multicollinearity can degrade statistical models, leading to flawed forecasts and misinformed business decisions.
When building or reviewing quantitative models, corporate leaders and quantitative analysts should adopt a systematic diagnostic protocol:
- Start with Sound Business Theory: Select explanatory variables based on clear theoretical mechanisms to prevent omitted variable bias and avoid including irrelevant predictors.
- Run Diagnostic Tests First: Routinely run the Ramsey RESET, Breusch-Pagan, White, Durbin-Watson, and VIF tests before relying on regression outputs for decision-making.
- Apply Robust Estimation Techniques: When assumptions are violated, use robust estimation methods—such as Huber-White robust standard errors for heteroskedasticity, Newey-West HAC adjustments for time-series correlation, and Ridge regularization for multicollinearity.
- Focus on Robustness Over Simple Fit: Do not rely solely on high values. A model with a slightly lower that satisfies classical Gauss-Markov assumptions will generate far more accurate out-of-sample predictions and decision-making guidance than an overfitted, misspecified model.
By applying these econometric principles, organizations can ensure that their quantitative models provide accurate, actionable insights for strategic decision-making.