Evaluating Regression Model Fit and Interpreting Model Results forms the cornerstone of empirical financial analysis, enabling portfolio managers, risk officers, and quantitative analysts to transform high-dimensional market data into actionable investment intelligence.
This comprehensive guide examines how investment professionals evaluate multiple regression models using Analysis of Variance (ANOVA) tables, assess goodness-of-fit metrics including  , Adjusted , and the Standard Error of Estimate, conduct joint hypothesis testing for subsets of regression coefficients, and calculate precise predicted values for asset returns and portfolio valuations.
Introduction to Multiple Regression in Investment Management
In modern quantitative finance, linear regression models serve as a fundamental tool for factor modeling, risk management, and asset valuation. Global financial institutions such as BlackRock, Inc. and JPMorgan Chase & Co. routinely construct multi-factor equity and fixed-income models to explain historical asset performance, isolate alpha generation, and stress-test portfolios against macroeconomic shocks.
A multiple linear regression model assumes a linear relationship between a dependent variable  (such as equity excess returns, credit default swap spreads, or portfolio risk premiums) and a set of
 explanatory independent variables
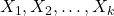 . The general population regression model is expressed as:

where  represents the intercept (often interpreted as unexplainable return or alpha in factor models),
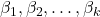 are the true slope coefficients measuring sensitivity to each factor, and
 represents an unobservable random error term with a expected mean of zero and constant variance
 .
To utilize these empirical models effectively for capital allocation, investment analysts must master three core quantitative tasks:
- Evaluating overall model explanatory power through Analysis of Variance (ANOVA) and statistical metrics of goodness of fit.
- Testing complex joint hypotheses regarding multiple regression parameters simultaneously.
- Calculating and interpreting point estimates and confidence intervals for future dependent variable outcomes.
Evaluating Regression Model Fit via ANOVA and Goodness of Fit Metrics
Evaluating Regression Model Fit and Interpreting Model Results begins with decomposing the variation of the dependent variable into explained and unexplained components. Analysis of Variance provides the mathematical framework for this structural breakdown.
Decomposition of Total Sum of Squares
Total variation in the dependent variable around its sample mean  is quantified by the Total Sum of Squares (
 ). In a multiple regression framework with
 sample observations, is partitioned into two mutually exclusive parts:
- Sum of Squares Regression (
 ): The portion of total variation in explained by the combined set of independent variables in the model.
- Sum of Squares Error (
 ): The residual portion of total variation in left unexplained by the regression model.
Mathematically, the identity is expressed as:

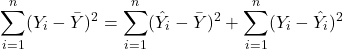
where  is the predicted value of the dependent variable for observation
 .
Structure of the Analysis of Variance (ANOVA) Table
The ANOVA table organizes these components alongside their respective degrees of freedom ( ), Mean Squares (
 ), and overall model test statistics. For a model with observations and independent variables, the structural ANOVA framework is defined as follows:
| Source of Variation | Sum of Squares (SS) | Degrees of Freedom (df) | Mean Square (MS) | F-Statistic |
| Regression (Explained) | | |  |  |
| Error (Unexplained) | |  |  | |
| Total | |  |
To illustrate with realistic quantitative finance data, consider an institutional equity quantitative model developed by research teams at Goldman Sachs Group, Inc.. The model predicts quarterly excess equity returns for technology hardware companies such as Apple Inc. using  historical quarterly observations (15 years) across
 explanatory variables: broad market excess return (
 ), semiconductor industry capital expenditure growth rate (
 ), and global real GDP growth rate (
 ).
The empirical regression output yields the following ANOVA table values:
| Source of Variation | Sum of Squares (SS) | Degrees of Freedom (df) | Mean Square (MS) | F-Statistic |
| Regression (Explained) | USD780.00 | 3 | USD260.00 | 34.67 |
| Error (Unexplained) | USD420.00 | 56 | USD7.50 | |
| Total | USD1,200.00 | 59 |
Calculation Details:


Measures of Goodness of Fit
Investment analysts rely on four primary statistical metrics derived from the ANOVA table to evaluate regression model fit.
1. Coefficient of Determination ()
The coefficient of determination measures the proportion of total variance in the dependent variable that is explained by the regression equation:
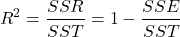
Using our quantitative model data:

Interpretation: Exactly 65.00% of the quarterly return variability for the technology hardware security is explained by the joint movement of broad market returns, semiconductor CapEx growth, and global GDP growth.
2. Adjusted Coefficient of Determination ( )
A fundamental mechanical flaw of unadjusted is that adding any new independent variable—even completely irrelevant noise—will never decrease , because cannot increase. To prevent artificial model over-fitting, analysts use Adjusted , which imposes a statistical penalty for each additional parameter added relative to sample size:

Substituting our sample values:

Key Takeaway: (63.13%) is strictly less than unadjusted (65.00%). If an analyst adds an irrelevant factor whose explanatory power fails to offset the loss of a degree of freedom, will decline, providing a reliable check against model over-parameterization.
3. Standard Error of the Estimate ( )
The Standard Error of the Estimate (also referred to as the standard error of residual error or  ) measures the dispersion of actual values around the regression line. It represents the standard deviation of the model residuals:


Interpretation: The provides an absolute measure of model inaccuracy in the same units as the dependent variable (percentage return points). Smaller values indicate tighter model fit and smaller prediction errors.
4. Overall Model  -Test
The overall -statistic tests whether the set of independent variables collectively explains a statistically significant portion of the dependent variable’s variance.
- Null Hypothesis (
 ):
 (The model has zero explanatory power).
- Alternative Hypothesis (
 ): At least one
 for
 .
The test statistic calculated from the ANOVA table is:

With numerator degrees of freedom  and denominator degrees of freedom
 , the critical -value at the 5% significance level (
 ) is approximately
 .
Because the calculated -statistic of  far exceeds the critical threshold of (with a
 -value
 ), portfolio managers reject and conclude that the regression model possesses significant collective explanatory power.
Hypothesis Testing on Multiple Coefficients and Joint Hypothesis Tests
Evaluating Regression Model Fit and Interpreting Model Results frequently requires testing hypotheses that involve multiple regression parameters simultaneously. While individual  -tests assess whether a single slope coefficient differs from zero holding all other variables constant, they are inadequate for testing the combined influence of a subset of variables.
The Limitations of Conducting Multiple Individual -Tests
Relying on separate -tests to evaluate a group of independent variables creates severe quantitative errors:
- Inflated Type I Error Rate: Running multiple independent hypothesis tests increases the cumulative probability of falsely rejecting at least one true null hypothesis (spurious statistical significance).
- Multicollinearity Distortion: When explanatory variables are correlated with one another—such as macroeconomic growth rates and industrial capital expenditures—individual -tests often fail to show statistical significance for individual factors due to inflated coefficient standard errors, even though the factors jointly exert a powerful, statistically significant impact.
To evaluate whether a subset of  independent variables collectively contributes meaningful explanatory power, analysts conduct a Joint Hypothesis Test using a restricted versus unrestricted model framework.
Formulating the Joint Hypothesis Test Framework
Suppose an investment research team analyzing microchip manufacturing firms such as ASML Holding N.V. wants to determine whether two macroeconomic factors—Semiconductor CapEx Growth () and Global GDP Growth ()—jointly improve the regression model over a baseline model containing only Broad Market Excess Return ().
The hypotheses for this joint test of  parameters are stated as:
- Null Hypothesis ():

- Alternative Hypothesis (): At least one of
 or

To execute this test, the analyst estimates two distinct linear equations:
- Unrestricted Model (Full Model): Contains all independent variables (
 ).
- Restricted Model: Imposes the constraints in (
 ), dropping and , leaving only (
 ).
Calculating the Partial -Test Statistic
The -statistic for a joint hypothesis test measures the relative reduction in unexplained variance () or the increase in explained variance () achieved by moving from the restricted model to the unrestricted model:

Equivalently, using coefficients of determination ():

where:
- = number of restrictions imposed by (number of variables omitted in the restricted model, here ).
- = total number of independent variables in the unrestricted model ().
- = sample size ().
Step-by-Step Empirical Execution of Joint -Test
Suppose the estimation of the Restricted Model (containing only ) produces the following performance parameters:


Recall the Unrestricted Model parameters from our earlier ANOVA analysis:


- Denominator

We now evaluate the joint -statistic using all three mathematical formulations to confirm consistency:
Method A: Via Sum of Squares Regression ()

Method B: Via Sum of Squares Error ()

Method C: Via Coefficient of Determination ()

Statistical Decision and Portfolio Management Interpretation
The degrees of freedom for this partial -test are:
- Numerator degrees of freedom (
 ) =
- Denominator degrees of freedom (
 ) =

Consulting the standard -distribution table at a 5% significance level (), the critical value  .
Because the calculated test statistic ( ) significantly exceeds the critical value of
 , we reject the null hypothesis
 at the 5% level.
Investment Conclusion: Omitting Semiconductor CapEx Growth () and Global GDP Growth () significantly degrades the model’s explanatory capabilities. Portfolio managers at quantitative asset management firms should retain both factors within their factor attribution systems rather than relying solely on single-factor market beta models.
Calculating and Interpreting Predicted Values for Dependent Variables
Beyond model evaluation and hypothesis testing, Evaluating Regression Model Fit and Interpreting Model Results requires using estimated regression parameters to make forward-looking projections for dependent variables. Quantitative asset managers use these forecasts for tactical asset allocation, stock selection, and stress testing.
The Estimation Equation
Given an estimated multiple regression model, the predicted (forecast) value of the dependent variable  is obtained by substituting assumed values for the independent variables into the parameter equation:

where  are the sample ordinary least squares (OLS) estimates of the population parameters.
Full Parameter Coefficient Table
Assume that OLS estimation of our tech equity return model yields the following coefficient estimates, standard errors, and individual -statistics:
| Parameter | Factor Description | Coefficient (β^j) | Standard Error (sβ^j) | Calculated t-Statistic | p-Value |
 | Intercept (Alpha) | 0.80% | 0.35% | 2.2857 | 0.0261 |
 | Market Excess Return () | 1.15 | 0.12 | 9.5833 | <0.0001 |
 | Semiconductor CapEx Growth () | 0.25 | 0.08 | 3.1250 | 0.0028 |
 | Global Real GDP Growth () | 0.80 | 0.32 | 2.5000 | 0.0154 |
The sample regression equation is expressed as:

Calculating the Point Estimate Prediction
Suppose a senior strategist at Microsoft Corporation or an equity research analyst evaluating auto manufacturers like Tesla, Inc. and Toyota Motor Corporation establishes the following baseline economic projections for the upcoming quarter:
- Broad Market Excess Return () =

- Semiconductor CapEx Growth () =

- Global Real GDP Growth () =

Substituting these input values into the estimated regression equation:


Point Estimate Interpretation: Given the scenario assumptions, the estimated multiple regression model forecasts a quarterly excess return of 8.90% for the target security.
Detailed Factor Contribution Breakdown
To better understand how each macroeconomic driver generates the predicted return, quantitative analysts construct factor attribution tables:
| Component | Assumed Value | Sensitivity Coefficient | Contributed Return | Percentage of Total Forecast |
| Intercept () | Baseline | 0.80% | 0.80% | 8.99% |
| Market Excess Return () | 4.00% | 1.15 | 4.60% | 51.69% |
| Semiconductor CapEx Growth () | 6.00% | 0.25 | 1.50% | 16.85% |
| Global Real GDP Growth () | 2.50% | 0.80 | 2.00% | 22.47% |
| Total Predicted Excess Return () | 8.90% | 100.00% |
Economic Insights:
- Market Sensitivity: Broad market excess performance (
 ) is the largest individual contributor, providing 4.60 percentage points (51.69% of the total predicted return), reflecting the asset’s cyclical market beta (
 ).
- Industry Capital Cycle: CapEx growth in semiconductors contributes 1.50 percentage points (16.85%), reflecting the sensitivity of hardware equipment producers to enterprise investment cycles.
- Macroeconomic Expansion: Global real GDP growth contributes 2.00 percentage points (22.47%), highlighting how top-line expansion drives semiconductor end-market demand.
- Model Alpha: The positive intercept of 0.80% represents abnormal return uncaptured by the three risk factors.
Constructing Prediction Intervals and Sources of Forecast Uncertainty
A point estimate ( ) provides a single expectation, but investment risk managers must account for uncertainty around forecasts. The variance of a forecast in regression analysis stems from two distinct sources:
- Uncertainty in Coefficient Estimates (Sampling Error): The sample estimates are random variables that deviate from true population parameters due to sampling variability.
- Uncertainty in Error Term (Inherent Random Noise): The model residual error term has variance estimated by
 .
The Standard Error of the Forecast ( ) incorporates both error components:


Suppose the calculated standard error of the forecast for this specific combination of independent variable values is  .
To construct a 95% Prediction Interval for an individual outcome of the dependent variable :

For  , two-tailed
 at is
 .


Risk Management Interpretation: Portfolio managers can state with 95% statistical confidence that under the assumed macroeconomic conditions ( ), the actual realized quarterly excess return for the asset will fall within the range of 2.69% to 15.11%.
Strategic Implementation in Quantitative Investment Strategies
Evaluating Regression Model Fit and Interpreting Model Results provides quantitative investment teams with a disciplined methodology for model validation, risk management, and tactical portfolio construction.
Comparing Model Performance Across Asset Classes
To highlight how goodness of fit and hypothesis testing metrics vary across investment applications, consider the following empirical benchmark comparison across major factor modeling strategies:
| Strategy Application | Dependent Variable (Y) | Key Independent Variables (Xk) | Typical R2 Range | Primary Diagnostic Focus |
| Equity Market Neutral Factor Models | Cross-sectional stock excess return | Value, Momentum, Quality, Size, Volatility factors | 10.00% – 25.00% | Adjusted , Joint -test on factor blocks |
| Fixed Income Spread Models | Corporate bond credit spread | Benchmark yield curve, Equity volatility, Leverage ratio | 65.00% – 85.00% | , Individual parameter -statistics |
| Macro Asset Allocation Models | Quarterly asset class index return | Inflation surprises, Real interest rates, Industrial output | 35.00% – 55.00% | Partial -test on macroeconomic subsets |
| Commodity Return Projections | Spot price changes | Inventory levels, USD index change, Freight indicators | 25.00% – 45.00% | Prediction interval width () |
Key Methodological Best Practices for Financial Analysts
When evaluating multiple regression models in institutional investment settings, analysts must follow key statistical guidelines:
- Always prioritize Adjusted over unadjusted when comparing nested regression models with different numbers of factors to avoid false inflation of model explanatory power.
- Examine the Standard Error of the Estimate () alongside to evaluate forecast precision in concrete return or currency terms rather than relying solely on relative variance ratios.
- Use Joint -tests instead of isolated individual -tests when evaluating correlated explanatory variables, such as macroeconomic or thematic factor blocks.
- Incorporate Prediction Intervals into Risk Frameworks rather than using point estimates alone, ensuring portfolio stress-testing accounts for forecast uncertainty.
By combining ANOVA evaluation, joint hypothesis testing, and scenario-based forecasting, quantitative practitioners build robust, mathematically sound models that drive consistent investment performance across global financial markets.