The integration of Machine Learning In Investment management has fundamentally altered how institutional investors, hedge funds, and asset managers process high-dimensional data, construct portfolios, and manage downside risk.
By automating the discovery of intricate patterns within complex financial datasets, Machine Learning In Investment allows capital allocators to transcend traditional econometric models and extract actionable alpha in highly competitive global markets.
This comprehensive analysis evaluates the primary paradigms of machine learning—supervised, unsupervised, and deep learning—examines the existential challenge of financial overfitting, and details the specific algorithms driving modern quantitative investment strategies.
Foundational Paradigms of Machine Learning In Investment
To effectively deploy computational models across financial markets, asset managers categorize machine learning architectures based on their learning mechanics, data requirements, and underlying optimization goals.
Supervised Machine Learning
Supervised machine learning algorithms learn a mapping function from input variables (features) to target outputs (labels) based on labeled historical training datasets. In quantitative finance, feature sets typically consist of fundamental ratios, macroeconomic indicators, technical signals, or alternative data points, while target labels represent future asset returns, credit default events, or volatility metrics.
Supervised learning tasks in investment are divided into two main categories:
- Regression Tasks: Used when the output label is a continuous numerical variable, such as predicting the 30-day forward return of an equity index, estimating a corporate bond’s yield spread, or forecasting interest rate movements.
- Classification Tasks: Used when the output label is categorical, such as classifying a company into credit default risk categories (e.g., Default vs. Non-Default) or predicting directional market movements (e.g., Up, Down, or Sideways).
Global financial institutions like JPMorgan Chase utilize supervised learning frameworks to enhance automated market-making engines, evaluate real-time creditworthiness across retail and corporate lending portfolios, and predict yield curve shifts.
Unsupervised Machine Learning
Unlike supervised learning, unsupervised machine learning operates on datasets without predefined target labels or explicit outcomes. The objective of unsupervised algorithms is to uncover hidden structures, underlying clusters, or latent dimensionality within complex financial datasets.
In institutional asset management, unsupervised learning fulfills critical functions:
- Dimensionality Reduction: Compressing hundreds of correlated financial indicators into a smaller set of uncorrelated factors without losing essential market information.
- Cluster Analysis: Grouping assets, market regimes, or client profiles based on statistical similarities rather than arbitrary industry definitions or legacy classifications.
Asset managers such as Vanguard leverage unsupervised learning to group fixed-income instruments with similar liquidity profiles, enhancing index tracking precision while minimizing transaction costs across portfolios totaling over USD8 trillion in assets under management.
Deep Learning
Deep learning represents an advanced subset of machine learning based on Artificial Neural Networks (ANNs) containing multiple hidden layers. These deep architectures automatically construct complex hierarchical representations of data, capturing highly non-linear relationships that traditional linear econometric models fail to identify.
Deep learning architectures used in quantitative finance include:
- Recurrent Neural Networks (RNNs) & Long Short-Term Memory (LSTM) Networks: Specifically designed for sequential time-series data, capturing long-term dependencies in market prices, tick-by-tick order book dynamics, and volatility clusters.
- Convolutional Neural Networks (CNNs): Applied to spatial data and grid-like financial data, such as analyzing satellite imagery of retail parking lots or shipping lanes to forecast quarterly revenue figures.
- Transformer Models & Natural Language Processing (NLP): Utilized to process vast volumes of unstructured text—including corporate earnings call transcripts, central bank policy statements, regulatory filings, and financial news streams—to derive real-time market sentiment scores.
Quantitative hedge funds like Two Sigma deploy deep learning architectures across alternative datasets to generate non-correlated return streams across global equity and futures markets, managing over USD60 billion in quantitative investment strategies.
Overfitting in Financial Data: Diagnostics and Mitigation Strategies
While modern computational models possess immense predictive capacity, their application to financial markets presents a significant operational hazard: model overfitting.
The Unique Nature of Financial Noise and Overfitting
Overfitting occurs when an algorithm learns the noise, randomness, and idiosyncrasies of historical training data rather than the underlying data-generating process. In an overfitted state, a model exhibits exceptionally low prediction error on historical in-sample data but fails catastrophically when deployed on out-of-sample live market data.
Financial time-series data is particularly susceptible to overfitting due to several distinct structural characteristics:
- Low Signal-to-Noise Ratio: Financial markets are influenced by structural randomness, behavioral biases, and unexpected macro shocks, making genuine predictive signals faint relative to background noise.
- Non-Stationarity: Market statistical properties (mean, variance, covariance) shift over time across different macroeconomic regimes, rendering past statistical relationships unstable.
- Data Mining Bias (Multiple Testing Hazard): Testing thousands of alternative signal combinations on the same historical dataset inevitably yields strategies that show high backtested returns purely due to random chance.
- Look-Ahead and Survivorship Bias: Inadvertently introducing future information into historical features or training models on datasets that exclude bankrupt companies artificially inflates backtested performance.
       [ Training Phase ]                      [ Deployment Phase ]
   In-Sample Data (Low Noise)              Out-of-Sample Data (Live Market)
+-------------------------------+      +-------------------------------+
| High In-Sample Accuracy       | ---> | Model Fails (High Drawdowns)  |
| Fits Noise + Signal Perfectly |      | Poor Generalization to Noise  |
+-------------------------------+      +-------------------------------+
Methodologies for Mitigating Overfitting
To prevent model breakdown and preserve capital, quantitative researchers employ rigorous statistical cross-validation and regularized modeling techniques.
Purged and Combinatorial Cross-Validation
Standard K-Fold cross-validation assumes independent and identically distributed (

Regularization Penalties
By incorporating mathematical penalty terms directly into the loss function, regularization constrains model complexity and discourages overly extreme parameter estimates.
Out-of-Sample Walk-Forward Optimization
Strategy parameters are fitted on a rolling historical window (e.g., 5 years) and tested on the immediate subsequent window (e.g., 6 months). The window then shifts forward in time, continuously testing the model on unseen data.
Early Stopping and Dropout Layering
In deep neural networks, early stopping halts the training process once validation error begins to diverge from training error. In parallel, dropout techniques randomly deactivate a subset of neurons during training passes, preventing individual nodes from co-adapting to random noise patterns.
Supervised Machine Learning Algorithms and Investment Applications
Supervised algorithms form the core framework of quantitative return forecasting, asset selection, and risk management systems.
Penalized Regression (Lasso, Ridge, and Elastic Net)
Penalized regression modifies standard Ordinary Least Squares (OLS) estimation by introducing regularization penalties to manage high-dimensional datasets where feature count approaches or exceeds observation count (

- Lasso Regression (

Lasso forces irrelevant feature coefficients to exactly zero, effectively conducting automated variable selection.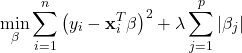
- Ridge Regression (

Ridge shrinks collinear feature coefficients toward zero without eliminating them, stabilizing predictions in highly correlated financial environments.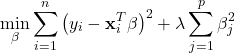
- Elastic Net: Combines both


Best-Suited Investment Problems: Macroeconomic factor return prediction, multi-factor fundamental equity scoring, and fundamental variable selection from large financial metric databases.
Support Vector Machines (SVM)
Support Vector Machines project input data into a higher-dimensional feature space using kernel functions (e.g., Radial Basis Function or Polynomial kernels) to identify an optimal decision boundary (hyperplane) that maximizes the margin between distinct classes.
Given training pairs 


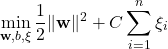

subject to 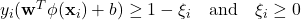

Best-Suited Investment Problems: Binary credit default prediction, sovereign debt rating transitions, directional market trend classification, and binary volatility regime switching.
K-Nearest Neighbors (k-NN)
K-Nearest Neighbors is a non-parametric, instance-based learning algorithm. To classify or forecast a target observation, k-NN calculates the distance (e.g., Euclidean or Manhattan distance) between the target feature vector and all historical instances, averaging the labels of the 

Best-Suited Investment Problems: Pricing illiquid securities (such as private equity assets or bespoke corporate bonds) by matching them to liquid peers, localized market micro-structure volatility estimation, and real-time execution cost analysis.
Classification and Regression Trees (CART)
CART models partition feature space into non-overlapping regions using a sequence of binary split rules. Splits are selected recursively to maximize node purity, measured by Gini Impurity or Entropy for classification tasks, and Variance Reduction for regression tasks.
While decision trees provide intuitive decision paths, standalone trees suffer from high variance, instability, and a tendency to overfit noisy financial datasets.
Best-Suited Investment Problems: Generating human-readable rule-based asset allocation trees, credit underwriting scoring frameworks, and qualitative risk screening models.
Ensemble Learning and Random Forests
Ensemble methods combine multiple individual models (weak learners) to construct a superior predictive model with lower variance and reduced bias.
- Bagging (Bootstrap Aggregation): Trains multiple decision trees independently on random bootstrap sub-samples of historical data and averages their predictions.
- Random Forests: Enhances Bagging by sub-sampling both data rows and feature columns at each split node. This decorrelates individual decision trees, significantly lowering model variance:
where


- Boosting (Gradient Boosting Machines, XGBoost, LightGBM): Trains decision trees sequentially. Each subsequent tree fits directly to the residual errors (gradients) of the ensemble models that preceded it.


Institutional managers such as Man Group deploy boosted tree ensembles across systematic active strategies to capture non-linear factor interactions, managing over USD175 billion in client capital.
Best-Suited Investment Problems: Multi-factor equity return forecasting, corporate earnings surprise predictions, high-frequency execution signal generation, and complex credit default risk modeling.
Unsupervised Machine Learning Algorithms and Investment Applications
Unsupervised algorithms enable investment managers to simplify complex market structures, isolate systemic risk drivers, and build diversified investment portfolios.
Principal Component Analysis (PCA)
Principal Component Analysis is a linear dimensionality reduction technique that transforms a set of correlated variables into a smaller set of uncorrelated orthogonal vectors called principal components. These components are ordered by the proportion of total dataset variance they explain.
The first principal component 

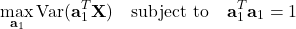

Subsequent components maximize remaining variance subject to orthogonality constraints against prior components.
Original Correlated Rates                Orthogonal Principal Components
 (30+ Maturity Yields)                     (Level, Slope, Curvature)
+-----------------------+                 +-----------------------+
| 1Y, 2Y, 5Y, 10Y, 30Y  |  == PCA ==>     | PC1: Yield Level (85%)|
| Highly Co-dependent   |                 | PC2: Yield Slope (10%)|
| Curve Metrics         |                 | PC3: Curvature   (3%) |
+-----------------------+                 +-----------------------+
Quantitative investment firms like AQR Capital Management utilize PCA to decompose yield curves, extract statistical arbitrage factors, and isolate macro risk exposures, managing over USD100 billion in alternative systematic funds.
Best-Suited Investment Problems: Fixed-income yield curve decomposition (isolating Level, Slope, and Curvature shifts), statistical arbitrage equity factor construction, and portfolio risk factor compression.
K-Means Clustering
K-Means is a partitioning algorithm that divides 


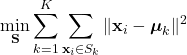

where 


Best-Suited Investment Problems: Reclassifying corporate stock universes based on statistical balance sheet metrics rather than legacy sector definitions, identifying macroeconomic regimes, and segmenting institutional client liquidity behavior.
Hierarchical Clustering
Hierarchical clustering constructs a nested tree of clusters (dendrogram) without requiring a pre-specified cluster count
- Agglomerative Clustering (Bottom-Up): Starts with individual observations as single clusters and iteratively merges the most statistically similar pairs based on distance metrics (e.g., Ward’s linkage, complete linkage).
- Divisive Clustering (Top-Down): Starts with the entire dataset as one cluster and recursively splits it into smaller sub-clusters.
Hierarchical Risk Parity (HRP)
Traditional Markowitz Mean-Variance Optimization requires inverting large variance-covariance matrices, rendering portfolio weights unstable when asset returns are highly collinear. Developed by Marcos López de Prado, Hierarchical Risk Parity applies hierarchical clustering to tree-structure asset correlation matrices. HRP allocates capital down the dendrogram tree hierarchy without matrix inversion, producing stable portfolio weights even during market crises.
Global macro managers like Bridgewater Associates leverage hierarchical allocation logic within risk-budgeting frameworks across global macro portfolios, managing over USD120 billion in institutional assets.
Best-Suited Investment Problems: Hierarchical Risk Parity portfolio construction, regime-dependent asset allocation, dynamic tail-risk hedging, and structural market network modeling.
Comparative Matrix of Machine Learning Algorithms in Asset Management
The following comparison details the operational trade-offs, analytical strengths, primary applications, and relative risk profiles of machine learning models used in modern asset management.
| Algorithm | Learning Paradigm | Primary Financial Application | Key Operational Advantages | Primary Model Limitations | Overfitting Sensitivity |
| Penalized Regression | Supervised (Regression) | Multi-factor variable selection & return forecasting | High interpretability; computationally efficient; handles | Cannot capture non-linear feature interactions | Low (controlled via  |
| Support Vector Machines | Supervised (Classification) | Credit default prediction & market regime detection | Effective in high-dimensional spaces; versatile kernel functions | High computational complexity on large datasets; sensitive to noise | Moderate (controlled via hyperparameter  |
| K-Nearest Neighbors | Supervised (Both) | Pricing illiquid bonds & trade cost matching | Non-parametric; simple implementation; no underlying distribution assumptions | High memory usage; computationally expensive during prediction phase | High (sensitive to parameter choice |
| Random Forests | Supervised (Both) | Multi-factor return prediction & risk scoring | Handles complex non-linear interactions; robust to outliers; estimates feature importance | Slower inference speed; lower model interpretability | Moderate (controlled via max tree depth) |
| XGBoost / LightGBM | Supervised (Both) | High-frequency signal synthesis & earnings surprises | Exceptional predictive performance; handles missing feature data | Prone to overfitting on noisy data; complex hyperparameter tuning | High (requires strict cross-validation) |
| Principal Component Analysis | Unsupervised (Reduction) | Yield curve modeling & statistical arbitrage | Eliminates multi-collinearity; compresses feature dimensions efficiently | Principal components lose direct business interpretability | Low (linear deterministic transformation) |
| K-Means Clustering | Unsupervised (Clustering) | Equity peer reclassification & regime detection | Scales easily to large datasets; simple algorithmic structure | Requires manual selection of | Moderate (sensitive to outlier data points) |
| Hierarchical Clustering | Unsupervised (Clustering) | Hierarchical Risk Parity (HRP) portfolio construction | Does not require matrix inversion; generates intuitive dendrogram tree structures | High computational complexity  | Low (stabilizes portfolio variance allocations) |


Conclusion: Strategic Imperatives for Institutional Investors
The deployment of Machine Learning In Investment processes has transitioned from a competitive advantage held by elite quantitative funds to an operational baseline across institutional asset management. When properly constrained by domain knowledge, robust out-of-sample cross-validation, and regularized algorithm selection, machine learning frameworks enable portfolio managers to extract structural alpha, optimize capital allocation, and systematically manage downside risk.
As alternative datasets expand and computing architectures mature, successful investment institutions will be those that effectively combine advanced machine learning techniques with rigorous statistical safeguards to navigate complex, evolving global capital markets.

